MCP Gateway vs Context Engine: Which One Your Agents Need, and Why It's Usually Both
A gateway governs how agents reach many MCP servers. A context engine changes what comes back. Most teams past a handful of servers end up wanting both.

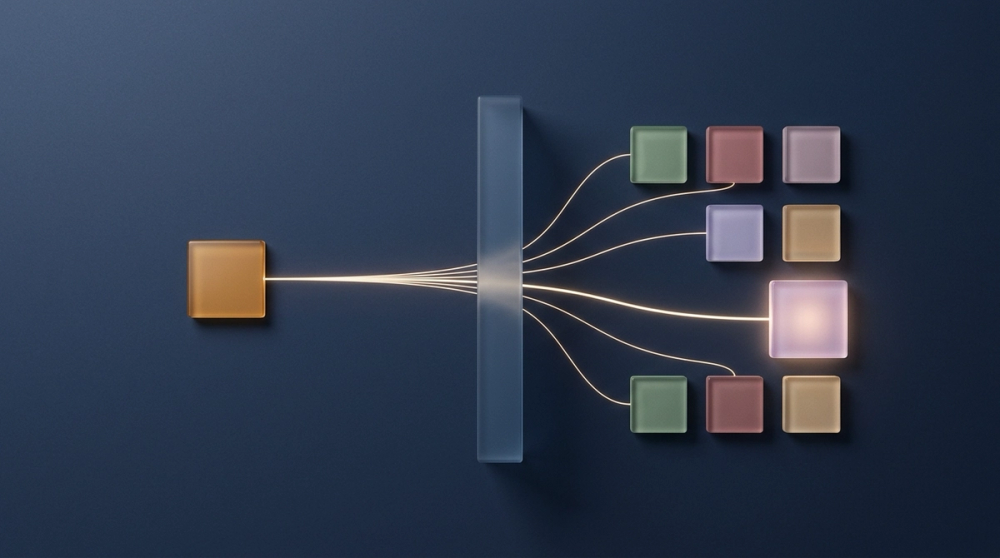
In brief: an MCP gateway governs the path between agents and tools. It authenticates, routes, rate-limits, logs and allow-lists. It never reads the results. A context engine exists to read the results for the agent, reconcile them across sources, and hand back one cited, permission-filtered answer. Teams with more than a handful of servers usually want the gateway for governance and the context engine as the one tool for the question of what the company knows.
An MCP gateway is a proxy that sits between your agents and many MCP servers to handle authentication, routing, rate limits, audit logs and tool allow-lists. A context engine is a service that ingests code, pull requests, tickets, docs and chat and returns one reconciled, cited, permission-filtered answer. Most teams past a handful of servers want both, because a gateway governs how an agent reaches tools while a context engine changes what the agent gets back. Anthropic's tool-search documentation puts a typical five-server setup (GitHub, Slack, Sentry, Grafana, Splunk) at roughly 55,000 tokens of tool definitions before the model does any work, and a gateway in front of those servers leaves that bill untouched.
MCP gateway vs context engine, what's the difference for agents?#
The difference is where each one acts. A gateway acts on the request path: it decides which agent may call which server, with which credentials, how often, and it logs the call. A context engine acts on the response: it decides what evidence the agent sees. The MCP project's own 2026 roadmap lists the enterprise gaps as audit trails, SSO-integrated auth and gateway behavior, all request-path concerns.
A worked example#
For example, picture an agent asking why the billing service retries three times. Through a gateway, that is still four calls: GitHub, Jira, Slack, Confluence. Four raw result lists come back and the agent reconciles them in its own context window. Through a context engine, it is one call, and what returns is a single answer that already weighed the merged PR against the stale Confluence page and cites both.
The gateway answers "may this agent reach this tool, and did it?" The context engine answers "what does the company know?" The broader version of that second question is in a context layer is not a context engine.
What does an MCP gateway actually do?#
An MCP gateway is a single endpoint that fronts many MCP servers and applies policy to every call passing through it. The vendors describe it in nearly identical terms. Docker calls its open-source gateway a "centralized proxy between clients and servers" that handles routing and authentication, injects credentials, and ships logging and call-tracing for governance.
Three gateways, one shape#
IBM's open-source ContextForge describes itself as a registry and proxy that "federates tools, agents, and APIs into one clean endpoint," with rate limiting, retries and OpenTelemetry tracing built in. Amazon's managed AgentCore Gateway offers one secure entry point for agentic traffic, ingress and egress authentication, built-in auditing, and a semantic tool search so agents can draw on thousands of tools without loading every definition.
Those are product facts from each vendor's own docs, and the shared shape is the point: a gateway makes a large tool estate governable. With the official MCP registry now listing servers from across the ecosystem, tool estates grow quickly, and governing them is a real need. What a gateway does not do is interpret results. Each server's output passes through unchanged, and every tool definition the gateway exposes still occupies context-window space on the agent side.
Is there such a thing as a context gateway for AI agents, an OpenRouter for context?#
Not in the sense people mean when they ask. OpenRouter gives applications "hundreds of AI models through a single API endpoint" and handles fallbacks automatically. The analogy breaks because routing a prompt to one model is a substitution problem: any model can answer. Routing a question to one of fourteen knowledge sources is a synthesis problem: the answer is spread across several of them and they disagree.
What the analogy gets right and wrong#
A gateway gives you the single-endpoint half of the analogy. What it cannot give you is the part people want, which is to ask once and receive one answer. The gateway forwards the question to whichever server the agent names and returns that server's raw list. The agent still chooses which sources to query, pays for every result it reads, and reconciles a Slack thread from last month against a design doc from last year.
That reconciliation is the job of a context engine, and it has to happen before the agent sees anything. Unblocked does it at ingestion. It maps identities across GitHub, Slack, Jira and SSO into one person, ranks code as the strongest evidence of current behavior, weighs recency and who said it, and enforces source permissions at query time. The closest honest phrase for that is the context engine for engineering, exposed to agents as one MCP tool that sits comfortably behind a gateway.
Why does adding more MCP servers make my agent worse?#
Because every server adds tool definitions the model must read on every turn, and selection accuracy falls as the list grows. The same Anthropic tool-search documentation cited above states that tool choice "degrades once you exceed 30–50 available tools," and that deferring definitions until needed cuts their token cost by over 85 percent. The degradation starts well before anything visibly breaks.
The measurements#
A May 2026 arXiv paper, "How Many Tools Should an LLM Agent See?", tested this directly. On a 370-tool benchmark, showing the model about 7 tools on average nearly matched the coverage of showing 50. A downstream check with Claude Sonnet 4.6 found tool-selection accuracy of 93.1% with short adaptive shortlists versus 87.1% with a fixed list of five. On medium-difficulty queries the gap widened to 76.8% against 60.9%.
The cost side compounds the accuracy side. Anthropic's own worked example puts five ordinary servers at roughly 55,000 tokens of definitions, more than a quarter of a 200,000-token window, before the agent reads a user message. Our tool overload piece collects the 2026 measurements. A gateway can allow-list and defer, which helps; the structural fix is to replace a dozen search-shaped tools with one that returns a finished answer.
Which concerns does each one own?#
Split the concerns by where they live. Request-path concerns belong to the gateway. The MCP authorization spec works at the transport level: where a server supports it, OAuth 2.1 is required and the server must not accept or pass on tokens meant for anyone else. Response concerns, meaning what the agent receives and whether it can trust it, belong to the context engine.
The split, row by row#
| Concern | Gateway | Context engine |
|---|---|---|
| Auth to tool servers | Yes, inbound and outbound credentials | Only for its own sources |
| Routing across servers | Yes, one endpoint fronts many | No, it is one tool |
| Rate limits | Yes, per client or server | Its own limits only |
| Audit of tool calls | Yes, every call logged | Logs questions and answers |
| Tool allow-lists | Yes, per agent or profile | Not applicable |
| What the agent receives | Raw results from each server | One reconciled, cited answer |
| Reconciling conflicting sources | No | Yes, by authority, recency and expertise |
| Permissions on content | Server-level access | Row-level, inherited from each source |
| Freshness | Whatever each server returns | Continuous ingestion from live sources |
| Token cost per answer | Unchanged, all definitions still load | Lower, one call replaces many |
Two rows carry most of the decision. "What the agent receives" is the line that separates plumbing from understanding, and "permissions on content" is the line most buyers miss until a private channel shows up in an answer.
How do they fit together?#
The stack is agent, then gateway, then many tools, and one of those tools is the context engine. We tested the difference in a same-prompt, same-model A/B run judged blind out of 50: one task on one codebase, run once with no MCP servers attached and once with a single Unblocked server attached. The arm with the context engine used 42% fewer tokens and 64% fewer tool calls. The judge, an LLM that did not know which run was which, scored it 41 against 24. One task, run once, so treat it as a worked example rather than a benchmark.
What the stack looks like in practice#
The agent authenticates once to the gateway, which holds the allow-list. That list might hold transactional servers, such as a Jira server for writes, a GitHub server for PR actions and a deploy server, plus a context engine for anything that starts with why, who or what happened before. For an action, the agent calls the transactional tool. For understanding, it calls the context engine once and gets back decision-grade context. Decision-grade context is context that has already been synthesized across sources, conflict-resolved, cited, and filtered to what the requesting user may see. The gateway logs both kinds of call the same way.
That is why the sibling piece on a pile of MCP connectors ends with customers running both. A gateway makes ten connectors governable without making them agree with each other.
My biggest use of Unblocked MCP has been AI governance — searching across Slack, fourteen Notion docs, S3, trying to understand where data lives and where the gaps are. There is no other way to humanly accomplish this task. It's an absolute godsend for getting context out of sources that don't talk to each other.
Gustavo Alvarez — Software Engineer, Sixfold
Frequently asked questions#
Do I need a gateway if I only run three or four servers?#
Probably not yet. Per-client allow-lists in your coding agent's config give you most of the governance at that size. The gateway earns its place when several teams share servers, credentials need central rotation, or security asks for one audit trail.
Can a context engine replace the gateway?#
No. A context engine is one tool among many. It does not authenticate your agent to the deploy server, rate-limit Jira, or log calls to tools it knows nothing about. It replaces the cluster of search-shaped tools, where most of the token cost and reconciliation work sits.
Does putting a context engine behind a gateway slow it down?#
Marginally, the same as any proxied call. The engine still does its ranking, conflict resolution and permission filtering server-side, so the agent's cost stays one call and one answer.
Which MCP servers should sit beside the context engine?#
Transactional ones, such as the servers that create the ticket, post the message, open the PR or trigger the deploy. Our comparison of MCP servers for engineering teams sorts the common ones by what they return. Keep read-everything search servers to a minimum; that is the job the engine took.
You probably need both#
If your agents reach more than a handful of MCP servers, run an MCP gateway for auth, routing, rate limits, audit and allow-lists. Run a context engine as the one tool those agents call when the question is what the company knows. The gateway keeps the estate governable, and the context engine keeps the answers correct, cited and scoped to what each person may see. In our testing it did so at 42% fewer tokens. Neither does the other's job, and the 2026 roadmap, the vendor docs and the tool-count research all point the same way: govern the path with one, change what comes back with the other.