What is the difference between a context engine and hooking Claude up directly to GitHub, Confluence and Slack MCPs?

Direct MCPs give Claude three search boxes and leave the work to the agent: which source to ask, how to rank what comes back, what to do when the wiki and the code disagree, and how much of it fits in the context window. A context engine does that work before the agent sees anything and returns one scoped, cited answer. Small team, one repo, little history: direct MCPs are enough.
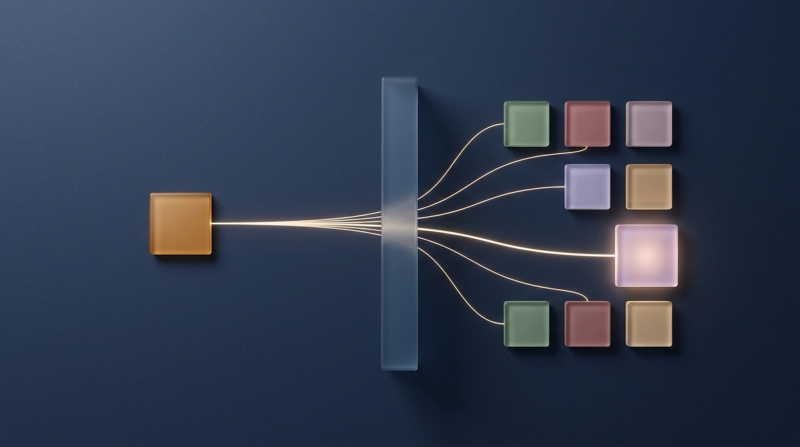
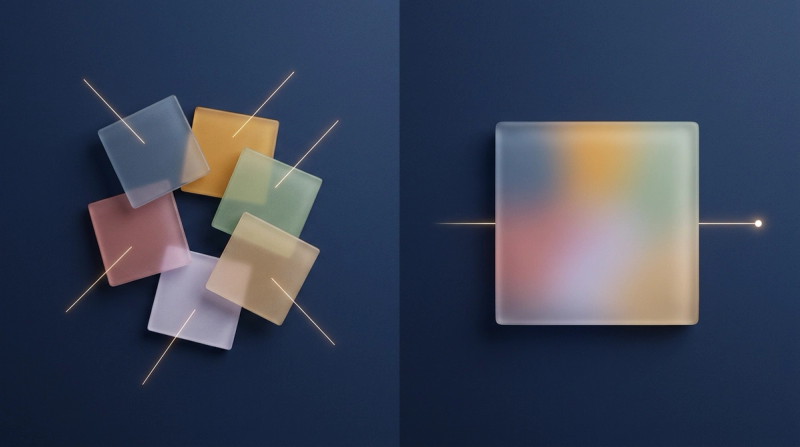
The difference is where the work happens. Hook Claude up to the GitHub, Confluence and Slack MCP servers and the agent gets three sets of raw tools. It picks which source to query, reads whatever comes back, ranks it, settles conflicts and pays for all of it in context. A context engine does that work before the agent sees anything and returns one cited answer. Direct MCP wiring is a setup where each source's MCP server is attached to the agent and the agent does its own retrieval across them. A context engine is a service that indexes code, PRs, tickets, docs and chat together, reconciles them, and returns one cited, permission-filtered answer over a single MCP connection. In brief: direct MCPs give the agent access, and a context engine gives it an answer.
| Direct GitHub, Confluence and Slack MCPs | Context engine | |
|---|---|---|
| What the agent receives | Three result lists, one per source | One cited answer with links to pull more |
| Tool definitions loaded | Dozens; about 55k tokens for a five-server setup | Two tools |
| When sources disagree | The agent decides, if it notices | Resolved server-side; real conflicts flagged |
| Who the tools run as | Whoever authorized each server | The asking user, filtered at query time |
| Setup per engineer | Three sign-ins; Slack admins approve each client | One install, one sign-in |
What the agent receives in each case#
With direct MCPs, the agent receives tool definitions, then search results. The MCP specification calls tools "model-controlled, meaning that the language model can discover and invoke tools automatically" (MCP specification). So the agent asks GitHub, then Confluence, then Slack, and gets three lists back in three formats. The model reads all of them to find the two paragraphs that matter.
With a context engine, the agent receives a finished answer. Unblocked's MCP server exposes two tools (Unblocked MCP docs). context_research is documented as "multi-source research across code, PRs, docs, issues, and messaging" that "returns a synthesized answer with citations," and context_get_urls fetches anything the citations point to. The result is "compact enough to fit its context window, with breadcrumbs to pull more" (inside the Unblocked context engine). See why a pile of MCP connectors is not a context engine for how the two shapes diverge.
What it costs in tokens and tool calls#
Tool definitions are the names, descriptions and input schemas every attached server loads into the context window at session start. Anthropic's docs say a typical setup of GitHub, Slack, Sentry, Grafana and Splunk "can consume ~55k tokens in definitions before Claude does any work" (Anthropic tool search docs). The same page says tool choice "degrades once you exceed 30–50 available tools." A March 2026 arXiv paper counted 121 tools across five MCP servers (arXiv 2603.20313). Claude Code warns when one tool output passes 10,000 tokens and caps it at 25,000 by default (Claude Code MCP docs). Three long search results can spend most of a turn on text the agent will discard.
A context engine spends those tokens once, server-side. In a controlled run on 2026-04-16 we measured the same prompt on the same model (claude-sonnet-4-6) against the same repository. With Unblocked attached the agent used 42% fewer tokens than with no MCP servers, and tool calls fell from 80 to 29 (same prompt, same model, different context). One run is not a population. Andrei Antanovich, Software Engineer at Waste Logics: "The first instruction in every agent project file is: before making any changes, gather context. That pulls from Jira, Confluence, and Slack via Unblocked — because that's where most of our knowledge actually lives, in threaded discussions. I set it up the day it was announced and now I don't even think about it. I just get the relevant information."
What happens when the wiki and the code disagree#
This is where direct MCPs quietly fail. For example, the Confluence page says the billing service retries three times, the code retries five, and a Slack thread from June explains the change. Through direct MCPs the agent gets all three as separate results with no signal about which is current. Often it takes the wiki, because the wiki reads like documentation and the thread reads like noise.
A context engine resolves that before the answer leaves the server. Ours treats code as "the strongest ground truth for how the system behaves right now" and weights recency for sources such as Slack. A "recent statement from the person the graph identifies as the domain expert" can override an older document. When sources genuinely conflict, "the engine says so rather than picking a side and hiding the disagreement" (inside the Unblocked context engine, linked above). The agent gets five retries, the PR that changed it, and the wiki page flagged as stale.
Permissions and setup: who the tools run as#
Each direct MCP runs as whoever authorized it. The GitHub MCP server signs you in with OAuth on first use or takes a personal access token (GitHub MCP server). Its tools "inherit the same access requirements as their corresponding GitHub features" (GitHub docs). Atlassian's remote MCP server uses OAuth 2.1 so calls "respect users' existing access controls and permissions" (Atlassian MCP docs). Slack scopes search to the user token, limits MCP to "apps published in the Slack Marketplace and internal apps," and has admins approve each client (Slack MCP docs). That is three OAuth flows per engineer, admin approval on the Slack side, plus a standing temptation to paste one shared token into a team config, after which every agent reads as the token's owner.
A context engine moves this to one managed connection. Unblocked's approach is to "flow access controls from the source" and enforce them "at query time, filtering retrieval down to what the asking identity is authorized to see" (inside the Unblocked context engine, linked above). One install script sets up the supported agents and opens a browser sign-in, so a platform team pushes one server and each engineer signs in once as themselves. The one MCP for Claude Code, Codex and Devin guide has the config for each agent.
When direct MCPs are enough#
Direct wiring is the right choice when the agent has nothing to reconcile. For example, a team of five with one repository, a Confluence space you can read in an afternoon, and Slack history measured in months has little for a context engine to resolve. Trim the GitHub server to its default toolsets, since its README notes that enabling only what you need can "reduce the context size," and keep Slack read-only.
The signal to move is the first time an agent confidently acts on the wrong source. That usually arrives with the second repository, the first engineer who leaves, or a wiki nobody has pruned in a year. The open question is who does the reconciling, and whether every engineer's agent does it alone.