How Enterprise AI Agents Get Company Context: Access Is Not Understanding
Connectors and MCP give enterprise AI agents access to GitHub, Jira, Slack and Confluence. Understanding how the company works is a separate job, and a shared context engine does it once for every agent.

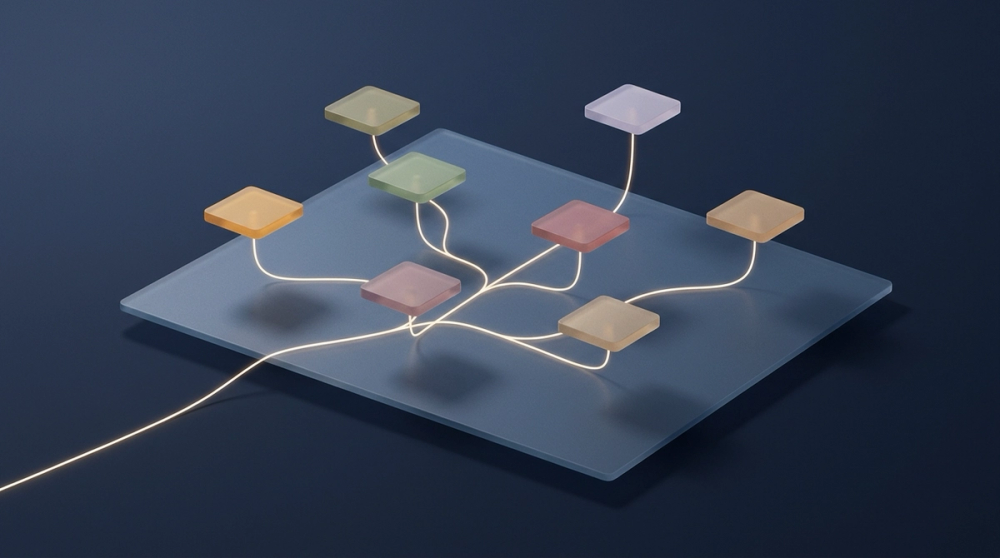
The short version: connectors and MCP servers hand an agent the raw contents of GitHub, Jira, Slack and Confluence, and the agent does the rest. Each agent decides where to look, which result to trust, and when to stop looking. A context engine does that work once, server-side, and serves the reconciled result to every agent and person who asks.
Enterprise AI agents get company context in one of two ways. Each agent can query GitHub, Jira, Slack and Confluence itself through connectors and work out what it all means. Or every agent can ask a shared layer that has already worked out how the company fits together. The problem is no longer intelligence. It's context. Models are capable enough. The next limit is whether the agent understands the company it works in: how systems relate, why decisions were made, which document is still true, who owns a service. Connecting more systems helps. An agent cannot reason about what it cannot reach. But access is only the start of the job. This post covers what connectors give agents, what they leave undone, and why a shared context layer for every agent and person is becoming infrastructure.
How do enterprise AI agents get company context from GitHub, Jira, Slack and Confluence?#
Mostly one connector at a time. Gartner's 2026 Hype Cycle for Agentic AI reports that only 17% of organizations have deployed AI agents so far, while more than 60% expect to within two years, citing its 2026 CIO and Technology Executive Survey (Gartner). Nearly all of those agents will read the same four systems, and most will read them directly.
What the vendor servers return#
The current MCP specification says servers offer three things to clients: resources ("context and data"), prompts, and tools (Model Context Protocol). GitHub's MCP server exposes repositories, issues and pull requests, and its tools "inherit the same access requirements as their corresponding GitHub features" (GitHub Docs). Atlassian's Rovo MCP Server lets a client search and update Jira and Confluence under OAuth 2.1 so that actions "respect users' existing access controls and permissions" (Atlassian Support). Slack's MCP server offers message, file and channel search behind user-token scopes such as search:read.private (Slack Docs).
A connector is a link to one system, often an MCP server, that returns documents from that tool in answer to a query the agent wrote. Each of these is a good one. Nothing in the protocol relates the Jira ticket to the pull request that closed it or the Slack thread that reversed it a week later. The mechanics of that gap are in why a pile of MCP connectors is not a context engine. This post is about what happens once you run many agents.
Do AI connectors give agents understanding of how the organization works, or just access?#
Access. Paragon's October 2026 survey of 600 B2B SaaS leaders found that 93%+ of agents need three or more integrations to be useful and 49% need six or more. Among respondents, 52% named integration reliability the top blocker to shipping agents (Paragon). Every added system is another one the agent has to reconcile on its own.
Give an agent four connectors and it still has four jobs before useful work starts. It has to decide where to look, which source wins when two disagree, how to reconcile them, and what matters for the task at hand. The stopping rule is where agents fail. The first plausible result becomes the answer the agent acts on, even when a better source sits one system over. Radiologists call that bias satisfaction of search; we described it in our write-up of how the engine works.
Why exhaustive search moves the cost#
Asking the agent to search everything moves the cost into longer reasoning loops. Anthropic's March 2026 context-engineering cookbook notes that when an agent calls tools, "the results become part of the conversation history and count against the context budget on every subsequent turn" (Claude Docs). A July 2026 synthesis of 27 agent-failure papers found that failures compound with task length. It lists long-horizon degradation from context accumulation as one of six recurring failure clusters (arXiv).
What does a connector provide, and what does a context engine add?#
A connector provides reach. A context engine is the layer that adds the reconciled answer: the same systems, indexed into one model, with conflicts resolved and permissions enforced before anything comes back. The Modern Data Company's interim survey results, published in August 2026 from 540-plus data leaders, show the gap. A 60.9% majority said a reliable context layer is necessary for AI agents, while only 8.4% said the data feeding their AI systems is trustworthy enough for production (Modern Data Company).
| Dimension | Per-source connector or MCP server | Context engine |
|---|---|---|
| Access | Raw documents from one system per query | The same systems, indexed all the time into one model |
| Source selection | The agent guesses which system and which query | Settled at indexing time from how the systems link to each other |
| Conflict resolution | First plausible result wins | Weighed by recency, authority and expertise, with citations |
| Permissions | One credential and one policy per connector, held by the agent | Source permissions mapped and enforced per person at query time |
| Freshness | Live per query, stale for anything not re-queried | Updates pushed by events across all sources |
| Token cost | Every search and dead end lands in the context window | The minimum context needed for the next decision, with breadcrumbs to go deeper |
The same rows separate a context layer you assemble by hand from an engine that reasons over the sources. See a context layer is not a context engine and what is a context engine. Connectors remain the right tool for reaching a system; the understanding is left to whoever calls them.
Is there a shared context layer for every AI assistant and agent in a company, instead of each one rebuilding it?#
Yes, and the larger the company, the sooner it needs one. McKinsey's State of AI 2026 found 40% of $1 billion-plus organizations are scaling AI agents in at least one function, up from 27%, while smaller organizations held at 22% (FM Magazine). Each of those agents needs to understand the company.
With a single assistant, rebuilding context on every request is wasteful. With dozens or hundreds of agents across the delivery lifecycle, each one deciding on its own where to look, what to trust and how to reconcile sources, that rebuilding becomes the limit. Anthropic's Managed Agents design (April 2026) separates a stateless harness, the brain, from sandboxes and tools, the hands, so that "brains can pass hands to one another" (Anthropic). Understanding of the company should be shared the same way.
What the shared layer has to do#
Picture the design as three bands. Bottom band: the systems of record: code, docs, chat, tickets, incidents, and business and operations data. Middle band: the context engine. It turns those sources into a living model of how the company works. It weighs each signal by how recent it is, who said it, who the expert is and who is allowed to see it, and returns the least context needed for the next decision. Top band: the consumers, a developer in Slack, a coding agent mid-task, a review bot, an incident investigator, each starting from the same understanding instead of rebuilding it. Decision-grade context is that output: pulled together, with conflicts settled and permissions enforced, the least an agent needs to make the next decision with confidence.
The permission half matters most in a shared layer. An April 2026 arXiv study of shared-state agents found benign interactions alone produced cross-user contamination rates of 57% to 71% under raw shared state (arXiv). A layer every agent reads from has to answer each query as the person asking, with source permissions enforced before anything leaves the server.
What does a platform for AI agents that write code, review PRs and investigate incidents with the same company knowledge look like?#
One context endpoint with many callers. Anthropic's 2026 Agentic Coding Trends Report predicts orchestrators coordinating specialized agents "each with dedicated context," and notes developers use AI in roughly 60% of their work yet "fully delegate" only 0 to 20% of tasks (Anthropic). Dedicated context per agent only works if each is filled from the same source.
What 141 customer organizations are building#
We analyzed 141 customer organizations in October 2026 and found six recurring workflow families built on the context layer. Ticket to researched plan to draft PR, for example, in 14 organizations. PR review with context and risk labels, in 12. Incident and CI-failure investigation, in 12. Support-ticket enrichment and internal Q&A, in 9. Scripted research with JSON receipts, in 5. QA and test generation, in 3. The finding across all six: the agent, CI runner or backend service owns the workflow and the actions, and the context layer owns why, who, and what happened before. The support and Q&A family has its own post, context for support and ops agents.
Unattended enterprise AI agents raise the stakes#
Webflow's remote agent platform, Flower, calls Unblocked over MCP when an agent's sandbox starts, alongside its other MCP servers. Russ Nealis calls it the most exciting of the set (Webflow customer story). A human at a terminal can catch a wrong turn in real time. An agent running unattended for hours cannot be corrected, so the context it starts from, and can return to mid-task, sets the ceiling on what comes back. For engineering teams that is the whole argument for Unblocked as the context engine for engineering: the research happens inside the engine, in parallel, before the agent spends a token on it.
What changes when people and agents share the same organizational understanding?#
Teams stop stitching sources together by hand, and the time it takes to own an unfamiliar system drops. Webflow's productivity org had gone all in on agentic development with Claude, Cursor and Codex before adopting Unblocked. Its customer story puts the gap plainly: access to information was never the real gap, understanding was. Unblocked now ranks among Webflow's top three engineering tools, with an 82 CSAT in the quarterly tool survey.
At RB Global, a newly formed platform engineering team took full ownership of a consultant-built platform in three months, against an expected six or more (RB Global customer story). Years of knowledge spread across Confluence, GitHub, Jira and Slack history became answerable. At Compare the Market, principal engineer James Ford says that without the engine his team would be "searching across systems, guessing keywords, and stitching it all together by hand". With it, the explanations "feel like they came from someone who knows our system" (Compare the Market customer story). Tradeshift's CTO put it bluntly:
You cannot make coding agents work without domain and functional context. We connected and trained Unblocked on our Code repos, Atlassian tools, Internal docs, Product Documentation, KB from Support and Slack history. When an agent asks a question, it gets the full picture — not just the code analysis, but also why decisions were made and what the constraints are. Other tools like Copilot know only the code. That's limited value. Unblocked is a game changer for Coding Agents.
Raphael Bres — CTO, Tradeshift
The gain is better decisions, by people and by enterprise AI agents, because both work from the same understanding.
FAQ#
Is MCP the wrong way to give enterprise AI agents company context?#
No. MCP is how Unblocked delivers context into Claude Code, Cursor, Codex, Copilot and remote agent platforms. The question is what sits on the other end of the connection: a single system's raw documents, or an engine that has already reconciled all of them.
Does a shared context layer mean every agent can see everything?#
No. Each query runs as the person asking, with permissions mapped from GitHub, Jira, Confluence, Slack and the rest and enforced at query time. Revoke access to a document at the source and the next answer no longer contains it.
Can we build this ourselves with RAG over Confluence and a vector index?#
You can build retrieval. The harder parts are settling conflicts across sources, an expertise model that knows whose recent statement outranks an older page, per-person permissions, and freshness driven by events. Every agent that skips the shared layer has to rebuild each of them.
How do we tell whether context is our limit rather than the model?#
Run the same task with the same model and harness twice, once with the context engine and once without, and compare time, tokens, correction loops and a blind judgment of quality. Our open-source context-engine-simulator does this against your own repository.
The next layer#
The first wave of enterprise AI helped people work faster. The next one changes how work gets done, with dozens or hundreds of agents writing code, reviewing pull requests, investigating incidents and updating docs. As that happens, understanding of the company stops being a feature of any one application and becomes shared infrastructure.
Identity took the same path when it became a base layer for enterprise software, and data platforms did when they became one for analytics. The job that remains is making sure every AI system and every person starts from the same understanding of how the company works. That is the role Unblocked is built for: the organizational understanding layer for enterprise AI.